
Key Takeaway
Localization testing is a distinct QA discipline that catches six specific categories of multilingual bugs – text truncation, placeholder failures, RTL layout breaks, plural rule mistakes, context-driven mistranslations, and script rendering issues – that generic functional testing consistently misses, regardless of how thorough the test suite appears.
TL;DR
Most multilingual bugs fall into six categories: text truncation and overflow from longer translated strings, placeholder and variable failures in dynamic content, RTL layout breaks in Arabic and Hebrew interfaces, plural rule mistakes in languages with complex grammar like Russian and Polish, context-driven mistranslations where UI strings are linguistically correct but functionally wrong, and script rendering issues affecting CJK characters and combining diacritics. Effective localization testing combines pseudo-localization running in CI on every build, automated placeholder validation at build time, and native-speaker LQA in staging. Automation typically catches 60–70% of surface-level localization bugs, while the remaining issues – tone, cultural appropriateness, and contextual accuracy – require human review.
Introduction
The pattern is familiar. A product team ships a release across multiple languages, passes all functional testing in the default language, and considers the build clean. Then the one-star reviews arrive. Users in Germany report clipped button labels. Users in Saudi Arabia see mirrored layouts that break navigation. Users in Poland encounter phrases like “1 items remaining.” None of these bugs would have surfaced in an English-only test suite, and none of them are translation errors in the traditional sense. They are localization bugs – technical defects that live at the intersection of code, layout, and language.
Localization testing verifies that software behaves correctly across every target locale, covering not just translation accuracy but also UI layout integrity, locale specific formatting, placeholder handling, plural logic, and script rendering. It is a testing discipline with its own methods, tools, and failure modes, distinct from both generic QA and linguistic review. For teams new to the broader discipline, read more about software localization in Crowdin’s blog for a comprehensive primer on what the practice involves end to end. This article builds on that context with a specific focus on the testing layer that catches multilingual bugs before they reach real users.
A localization testing playbook outlines the strategy and standards for software testing across cultural markets. It serves as a reusable organizational asset for consistency across product teams, and a well-designed playbook should evolve with new market needs and product features. This playbook covers the six bug categories that account for the majority of multilingual defects, the testing framework that maps each check to the right stage of the development process, and the practical trade-offs between automated testing and human review. Localization testing should be part of the software development lifecycle – not bolted on at the end.
Why Localization Testing Is a Distinct Discipline
Generic quality assurance validates that features work. Localization testing asks whether those features work correctly in every target language, for every target audience, across every target culture the product serves. The distinction matters because each layer catches different defect types.
Linguistic testing checks translation accuracy and cultural appropriateness – grammar, terminology, tone. Functional testing verifies locale-specific behavior and UI functionality – whether date pickers render the right format, whether sorting respects local collation rules, whether error messages display correctly in the local language. Cosmetic testing focuses on visual correctness of the UI with translations, catching overlapping elements, truncated labels, and misaligned layouts. Cultural testing evaluates appropriateness of visuals and symbols for local markets. Formatting testing checks currency, date, and number formats for locales. Localization testing covers all five of these dimensions, which is why it requires its own process, its own testing environment, and its own ownership within the team.
LQA is not a synonym for translation review. A translated string can score perfectly on linguistic accuracy and still produce a broken user experience if it overflows a button, drops a placeholder variable, or renders in the wrong script variant. Localization testing ensures that the full pipeline – from source language through the translation management system to the rendered UI – produces correct, complete, usable localized versions in every supported locale.
The Six Categories of Multilingual Bugs
Text Truncation and Overflow
German compound words and Finnish noun forms routinely exceed the character length of their English equivalents by 30–50%. Fixed-width buttons, table headers, and navigation labels clip or overflow when they encounter these longer translated strings. Without testing with expanded text, teams only discover truncation after localized content reaches production.
Placeholder and Variable Failures
Dynamic content insertion – usernames, counts, dates – depends on placeholders like {0}, %@, or {username} surviving translation intact. Translators may accidentally delete, reorder, or duplicate placeholders. Worse, string concatenation in code (building sentences by joining fragments) produces invalid grammar in languages where word order differs from English, creating formatting errors that are technically correct in the source language but broken in the target language.
RTL Layout Breaks
Arabic and Hebrew require full UI mirroring: navigation flows right to left, scrollbars shift sides, button order reverses. When CSS direction attributes or mobile layout constraints do not account for RTL, the interface breaks – back buttons appear on the wrong side, padding and margins render asymmetrically, and bidirectional text mixing (English terms embedded in Arabic sentences) produces garbled output.
Plural Rule Mistakes
English has two plural forms: singular and plural. Russian requires four categories (one, few, many, other). Arabic uses six. ICU MessageFormat and CLDR plural rules handle this complexity, but only when developers define all required categories. Hardcoded if count == 1 logic – the most common shortcut – fails silently in languages with complex plural systems, producing ungrammatical UI strings at specific counts like 2, 5, 11, or 22.
Context-Driven Mistranslations
The English word “Save” translates differently depending on whether it labels a button that writes data to disk or one that bookmarks content. Ambiguous UI strings reused across multiple contexts produce translations that are linguistically accurate but contextually wrong. Without developer-provided context – screenshots, usage notes, screen identifiers – translators guess, and guesses accumulate into inconsistent, confusing localized pages.
Script Rendering Issues
CJK ideographs may display the wrong regional variant (simplified vs. traditional Chinese). Vietnamese combining diacritics may stack incorrectly when fonts lack proper OpenType support. Missing glyphs render as empty boxes (tofu). These script rendering failures stem from encoding pipeline issues, font coverage gaps, and normalization mismatches (NFC vs. NFD) that only surface when the product runs in the affected locale specific environment.
The Testing Framework: When Each Test Runs
Localization testing is most effective when distributed across the entire development process rather than concentrated at the end. A mature localization workflow maps specific checks to specific pipeline stages:
- During development (feature branch): Pseudo-localization runs in CI on every build. Developers see expanded, accented, and mirrored text in their local environment, catching overflow, hardcoded strings, and missing internationalization properties before code review.
- At build time: Automated placeholder validators scan string resource files, flagging mismatched variable counts, missing plural categories, and file format errors. Run a full locale-specific test suite after each translation import.
- After translation delivery: Length and terminology checkers verify that translated strings fit UI constraints and match the approved term base. Automated tools check for missing translations and formatting errors.
- In staging (pre-release builds): Native-speaker LQA testers perform in-context review – running the application in each target locale, verifying layout, script rendering, cultural appropriateness, and functional correctness. Use a checklist during QA passes on any localized build.
- Post-release: Monitor app store reviews, crash logs, and user feedback filtered by locale. Locale-specific crashes and complaints feed back into the testing process for the next cycle.
Automated Localization Testing Approaches
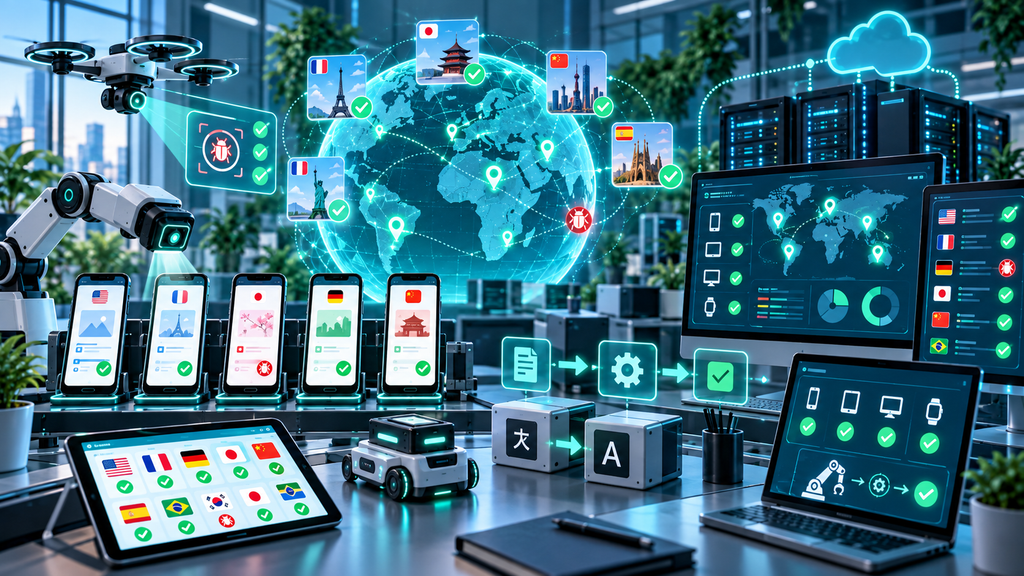
Automate localization testing to save time and ensure consistency. Automation handles the high-volume, repetitive checks that would be impractical to run manually across multiple locales, freeing human testers for judgment-intensive work.
Pseudo-localization is a valuable automated localization testing technique. It transforms source strings by expanding length (typically 30–40%), inserting non-ASCII characters, and simulating RTL mirroring – all without requiring real translation. Integrated into CI/CD, it reveals internationalization testing gaps on every commit. Tools like PseudoLoc and Globalyzer automate localization testing tasks of this kind.
Placeholder validation scripts compare source and target resource files, flagging any translated strings where variables have been dropped, duplicated, or reordered. Length constraint checkers verify that translations fit within defined character or pixel limits for each UI component. Terminology enforcement tools cross-reference translations against approved glossaries to maintain translation quality and consistency across localized versions. Visual regression testing renders components in each target locale and compares screenshots to baselines, catching layout drift, overlapping elements, and truncation.
Automation typically catches 60–70% of surface-level localization bugs. The remaining defects – contextual mistranslations, tone mismatches, cultural differences, and subtle script rendering artifacts – require human judgment.
Human Localization QA: When Automation Isn’t Enough
The human LQA layer validates what machines cannot: whether localized content feels right to a native speaker in the target culture. This is where linguistic testing, cultural relevance assessment, and contextual validation converge.
Native speakers serving as LQA testers should be fluent in the target language, resident in the target market (to understand dialect and cultural norms), and experienced with software UI conventions. They review translations in context – running the product, navigating flows, and flagging instances where translation accuracy is high but user experience suffers due to formality mismatches, ambiguous phrasing, or culturally inappropriate imagery or symbols.
Crowdtesting platforms connect you with expert testers globally, providing access to local experts across markets that would be difficult to staff in-house. Translation management systems streamline localization workflows and track changes, giving LQA testers visibility into what has changed since the last review. For major releases spanning multiple languages, allocating a two-week LQA phase before staging lock provides enough time for native-speaker review and engineering fixes. Localization teams can then review translations, validate locale specific behavior, and sign off before release with confidence.
Common Mistakes That Let Multilingual Bugs Reach Production
- Testing only with English-length assumptions. English strings are often the shortest variant. Manual testing that never exercises longer translations misses truncation bugs entirely. Fix: run pseudo-localization with 40% text expansion on every build.
- Skipping pseudo-localization during development. Without it, internationalization testing defects hide until real translations arrive – when fixing layout is expensive. Fix: integrate pseudo-localization into CI from the first sprint.
- Running LQA too late in the release cycle. When human review happens days before ship, there is no time to fix what testers find. Fix: schedule LQA parallel to development, not sequential after feature freeze.
- Ignoring locale-specific functionality. Date formats, measurement units, postal codes, currency placement, and regional formatting vary across multiple countries. Fix: maintain locale-specific test cases that validate these behaviors explicitly.
- Treating localization testing as optional. Teams that perform localization testing only for top-revenue target markets accumulate defects in secondary locales, eroding user satisfaction and brand trust. Fix: establish minimum LQA coverage for every shipped locale.
Best Practices for a Modern LQA Process
- Integrate pseudo-localization into CI from day one of the development process, treating it as standard as linting or unit testing.
- Establish clear LQA ownership – assign a localization testing lead who coordinates across localization teams, engineering, and translation vendors.
- Automate repetitive validation checks: placeholder matching, length constraints, missing translations, and terminology enforcement using automated tools.
- Maintain locale-specific test environments that mirror production device diversity, screen sizes, and OS versions for each target locale.
- Document and track localization-specific test cases as part of the regression suite, so they run on every release – a localization testing checklist that scales with the product.
- Plan LQA phases parallel to development sprints, not as a sequential gate at the end. Localization testing reduces costly post-launch fixes by catching errors early and improves user experience across different regions.
Frequently Asked Questions
What is Linguistic Quality Assurance (LQA)?
LQA combines linguistic verification – checking translation accuracy, grammar, and tone consistency – with technical validation of how translated strings render in the UI. It goes beyond human translation review to include layout checks, placeholder verification, and cultural appropriateness assessment. Its primary focus is ensuring localized versions meet both linguistic accuracy and functional standards.
How is localization testing different from generic QA?
Generic software testing validates features in the default language. Localization testing verifies that those features work correctly in every specific locale – checking locale specific formatting, script rendering, dynamic content insertion, plural logic, and cultural relevance. It catches bugs that only manifest in localized versions, which generic QA cannot surface.
What is pseudo-localization?
Pseudo-localization is an automated technique that transforms source strings to simulate translation characteristics – expanding text length, inserting non-ASCII characters, and mirroring layout for RTL – without requiring actual human translation. It reveals internationalization defects like overflow, hardcoded strings, and missing resource externalization early in the testing process.
How much does LQA cost?
Costs depend on locale count, content volume, and device coverage. Many localization programs find that investing in automation and a translation management system reduces per-release effort significantly. Industry case studies report reductions from roughly 84 hours to 14 hours per release when mature pipelines combine automated testing with targeted manual testing by native speakers.
Can AI replace human LQA testers?
AI and machine translation tools assist with surface-level checks – placeholder validation, terminology consistency, formatting errors – but cannot reliably assess tone, cultural differences, contextual meaning, or regulatory compliance. Human review remains essential for customer-facing and culturally sensitive localized content. AI augments human LQA rather than replacing it.
How long should an LQA phase take?
For major multi-locale releases across 20 or more languages, plan roughly two weeks for in-context human review plus engineering fixes. Smaller releases with fewer locales may need several days. The phase must include buffer time so defects found during review can be resolved without delaying the release.
Conclusion
Localization testing is a high-ROI localization investment. It prevents costly misinterpretations and user rejection, ensures compliance with local regulations and standards, enhances brand reputation by aligning with local cultural expectations, and increases market reach by making products more accessible to international users across multiple countries.
The discipline requires its own methods, its own timing within the software development lifecycle, and its own balance of automation and human judgment. Teams that treat it as an afterthought discover bugs through user feedback. Teams that build it into their localization strategy discover those same bugs in staging, where fixing them costs a fraction of a post-release patch.
For deeper technical guidance on the internationalization standards that underpin every localization testing framework, the W3C Internationalization Working Group publishes authoritative reference material on scripts, character sets, text direction, and locale identification – the foundational layer every mobile framework and web platform builds on.
Start with pseudo-localization in CI, define your six bug categories as test case families, and schedule human LQA early enough to act on what testers find. The playbook works when it runs continuously – not when it sits in a wiki unread.

